Research
 LongListBench: A Benchmark for Long-List Entity Extraction from Complex Business PDFs
An open benchmark for complete document-to-list extraction: 32 synthetic business PDFs, 29,599 target records, 14 auditable stressors, OCR transcripts, and strict completeness scoring. Four agentic baselines recover 94.5–97.9% of records exactly — yet complete only 4–9 of 32 documents.
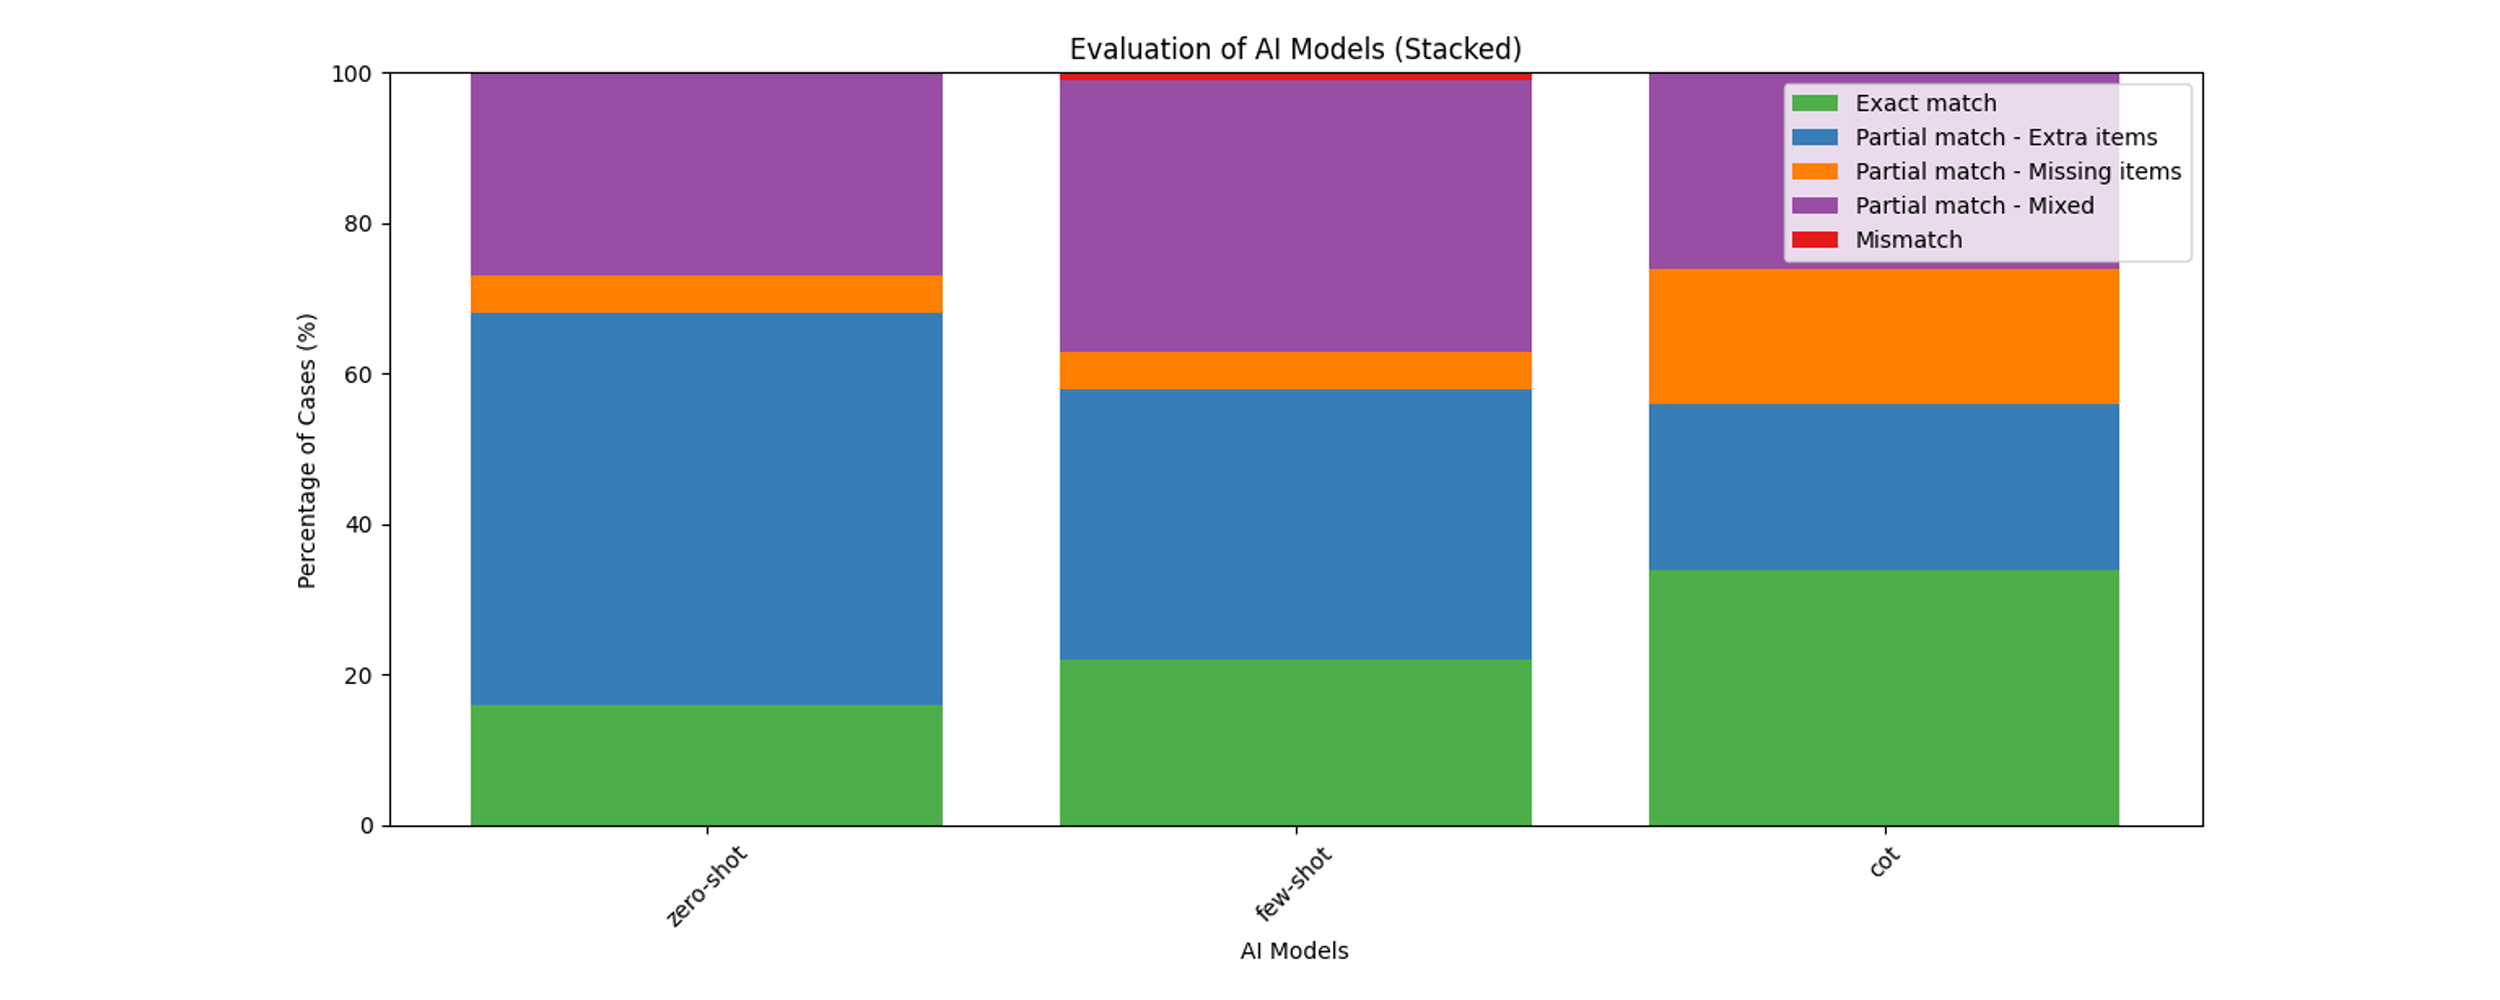 AI-Facilitated Software Project Generation from Natural Language Using Curated Code Snippets
Maps natural-language project descriptions to curated, reusable code snippets instead of relying on unconstrained generation — chain-of-thought prompting lifted snippet-mapping accuracy from 30.3% to 43.1%.
At Hypha I'm researching agent tool design: how the shape of a tool changes what an agent can do reliably. A paper on agentic browser automation is in preparation. Looking for the engineering posts? See Writing.