Writing
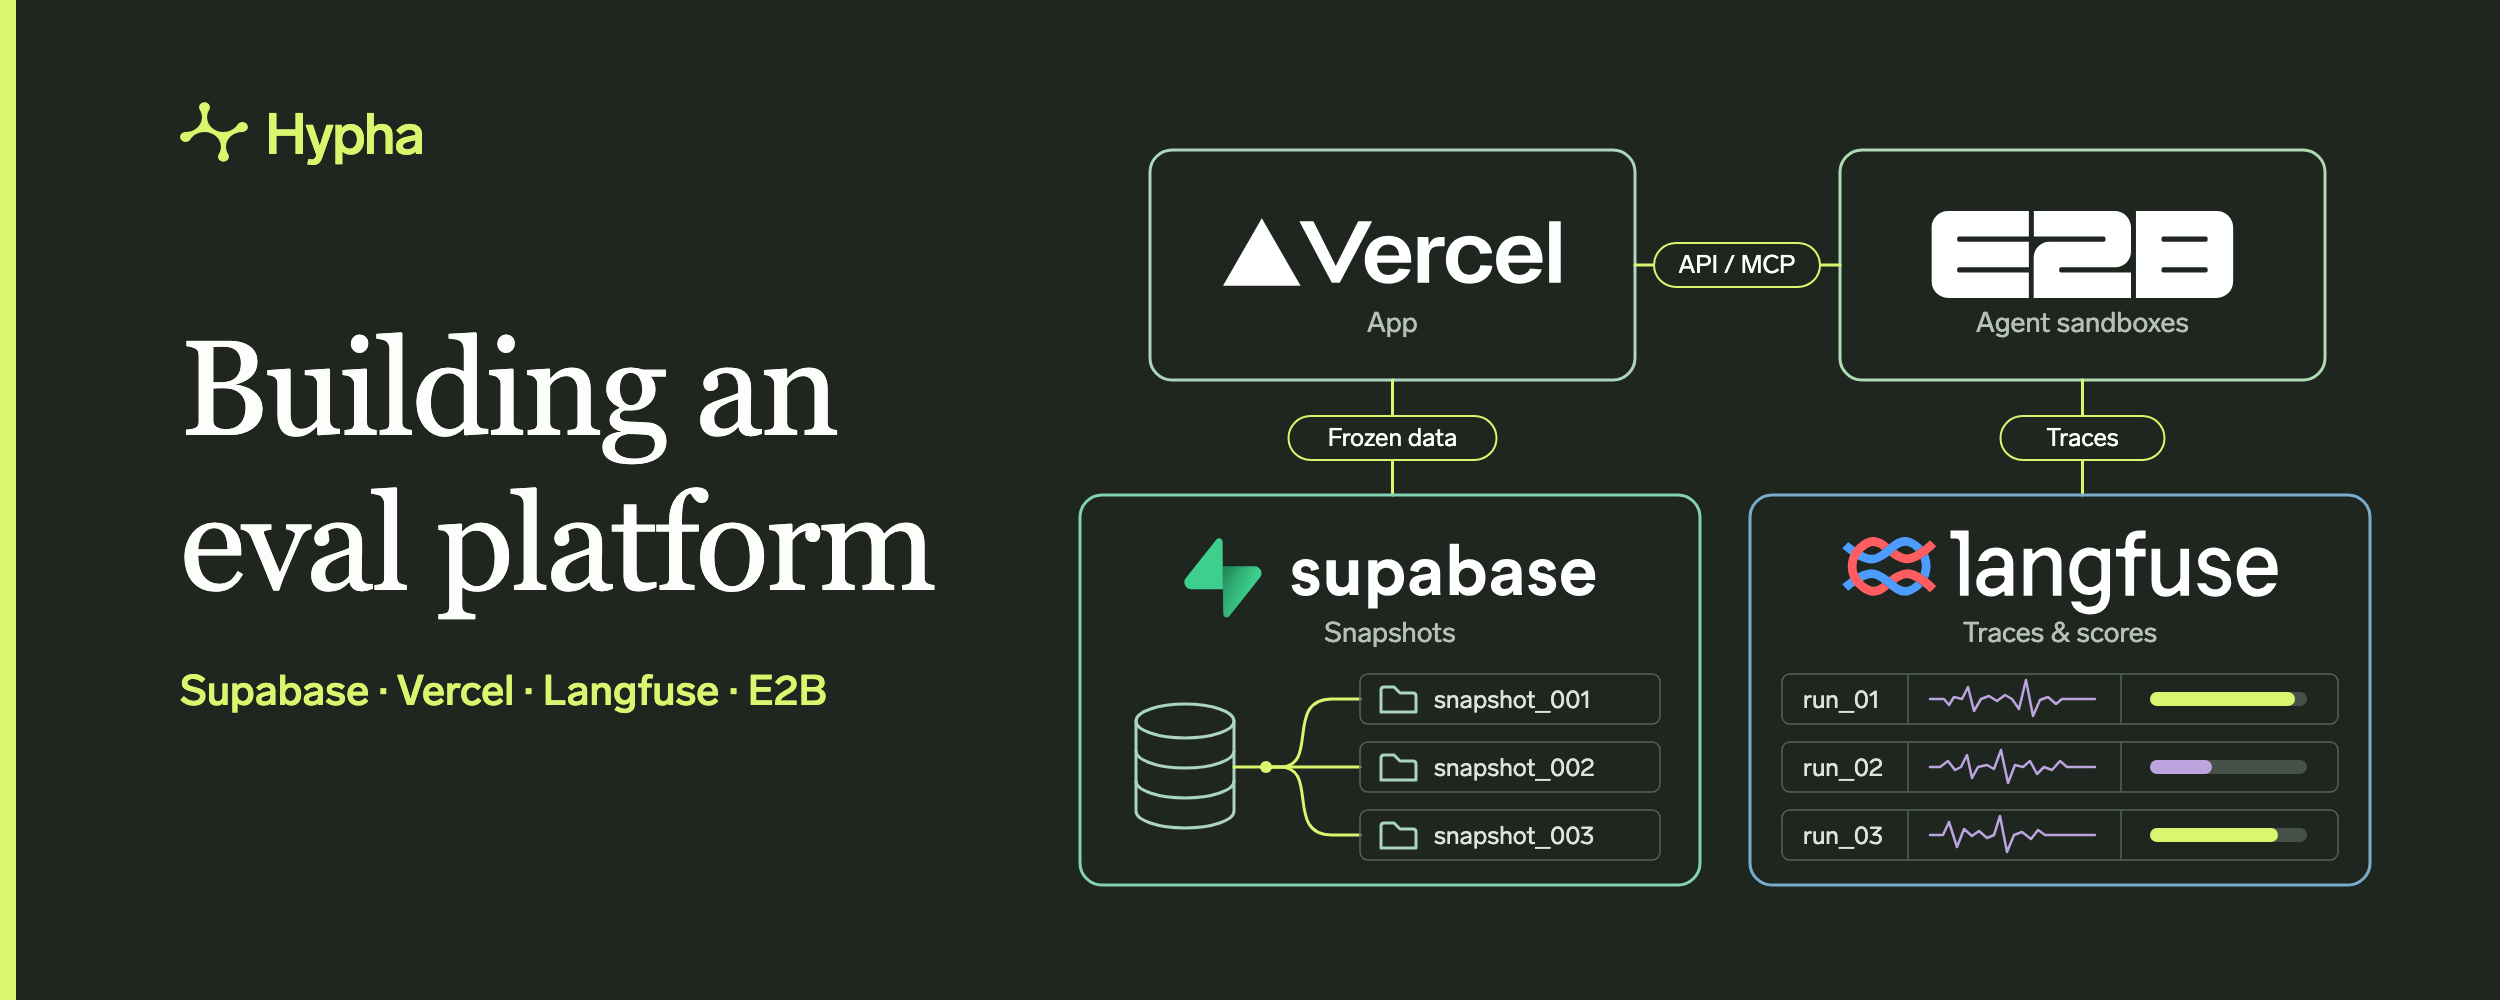 Building an eval platform
Shared interfaces, reproducible data, cloud runs and scoring. How we built Hypha's eval framework.
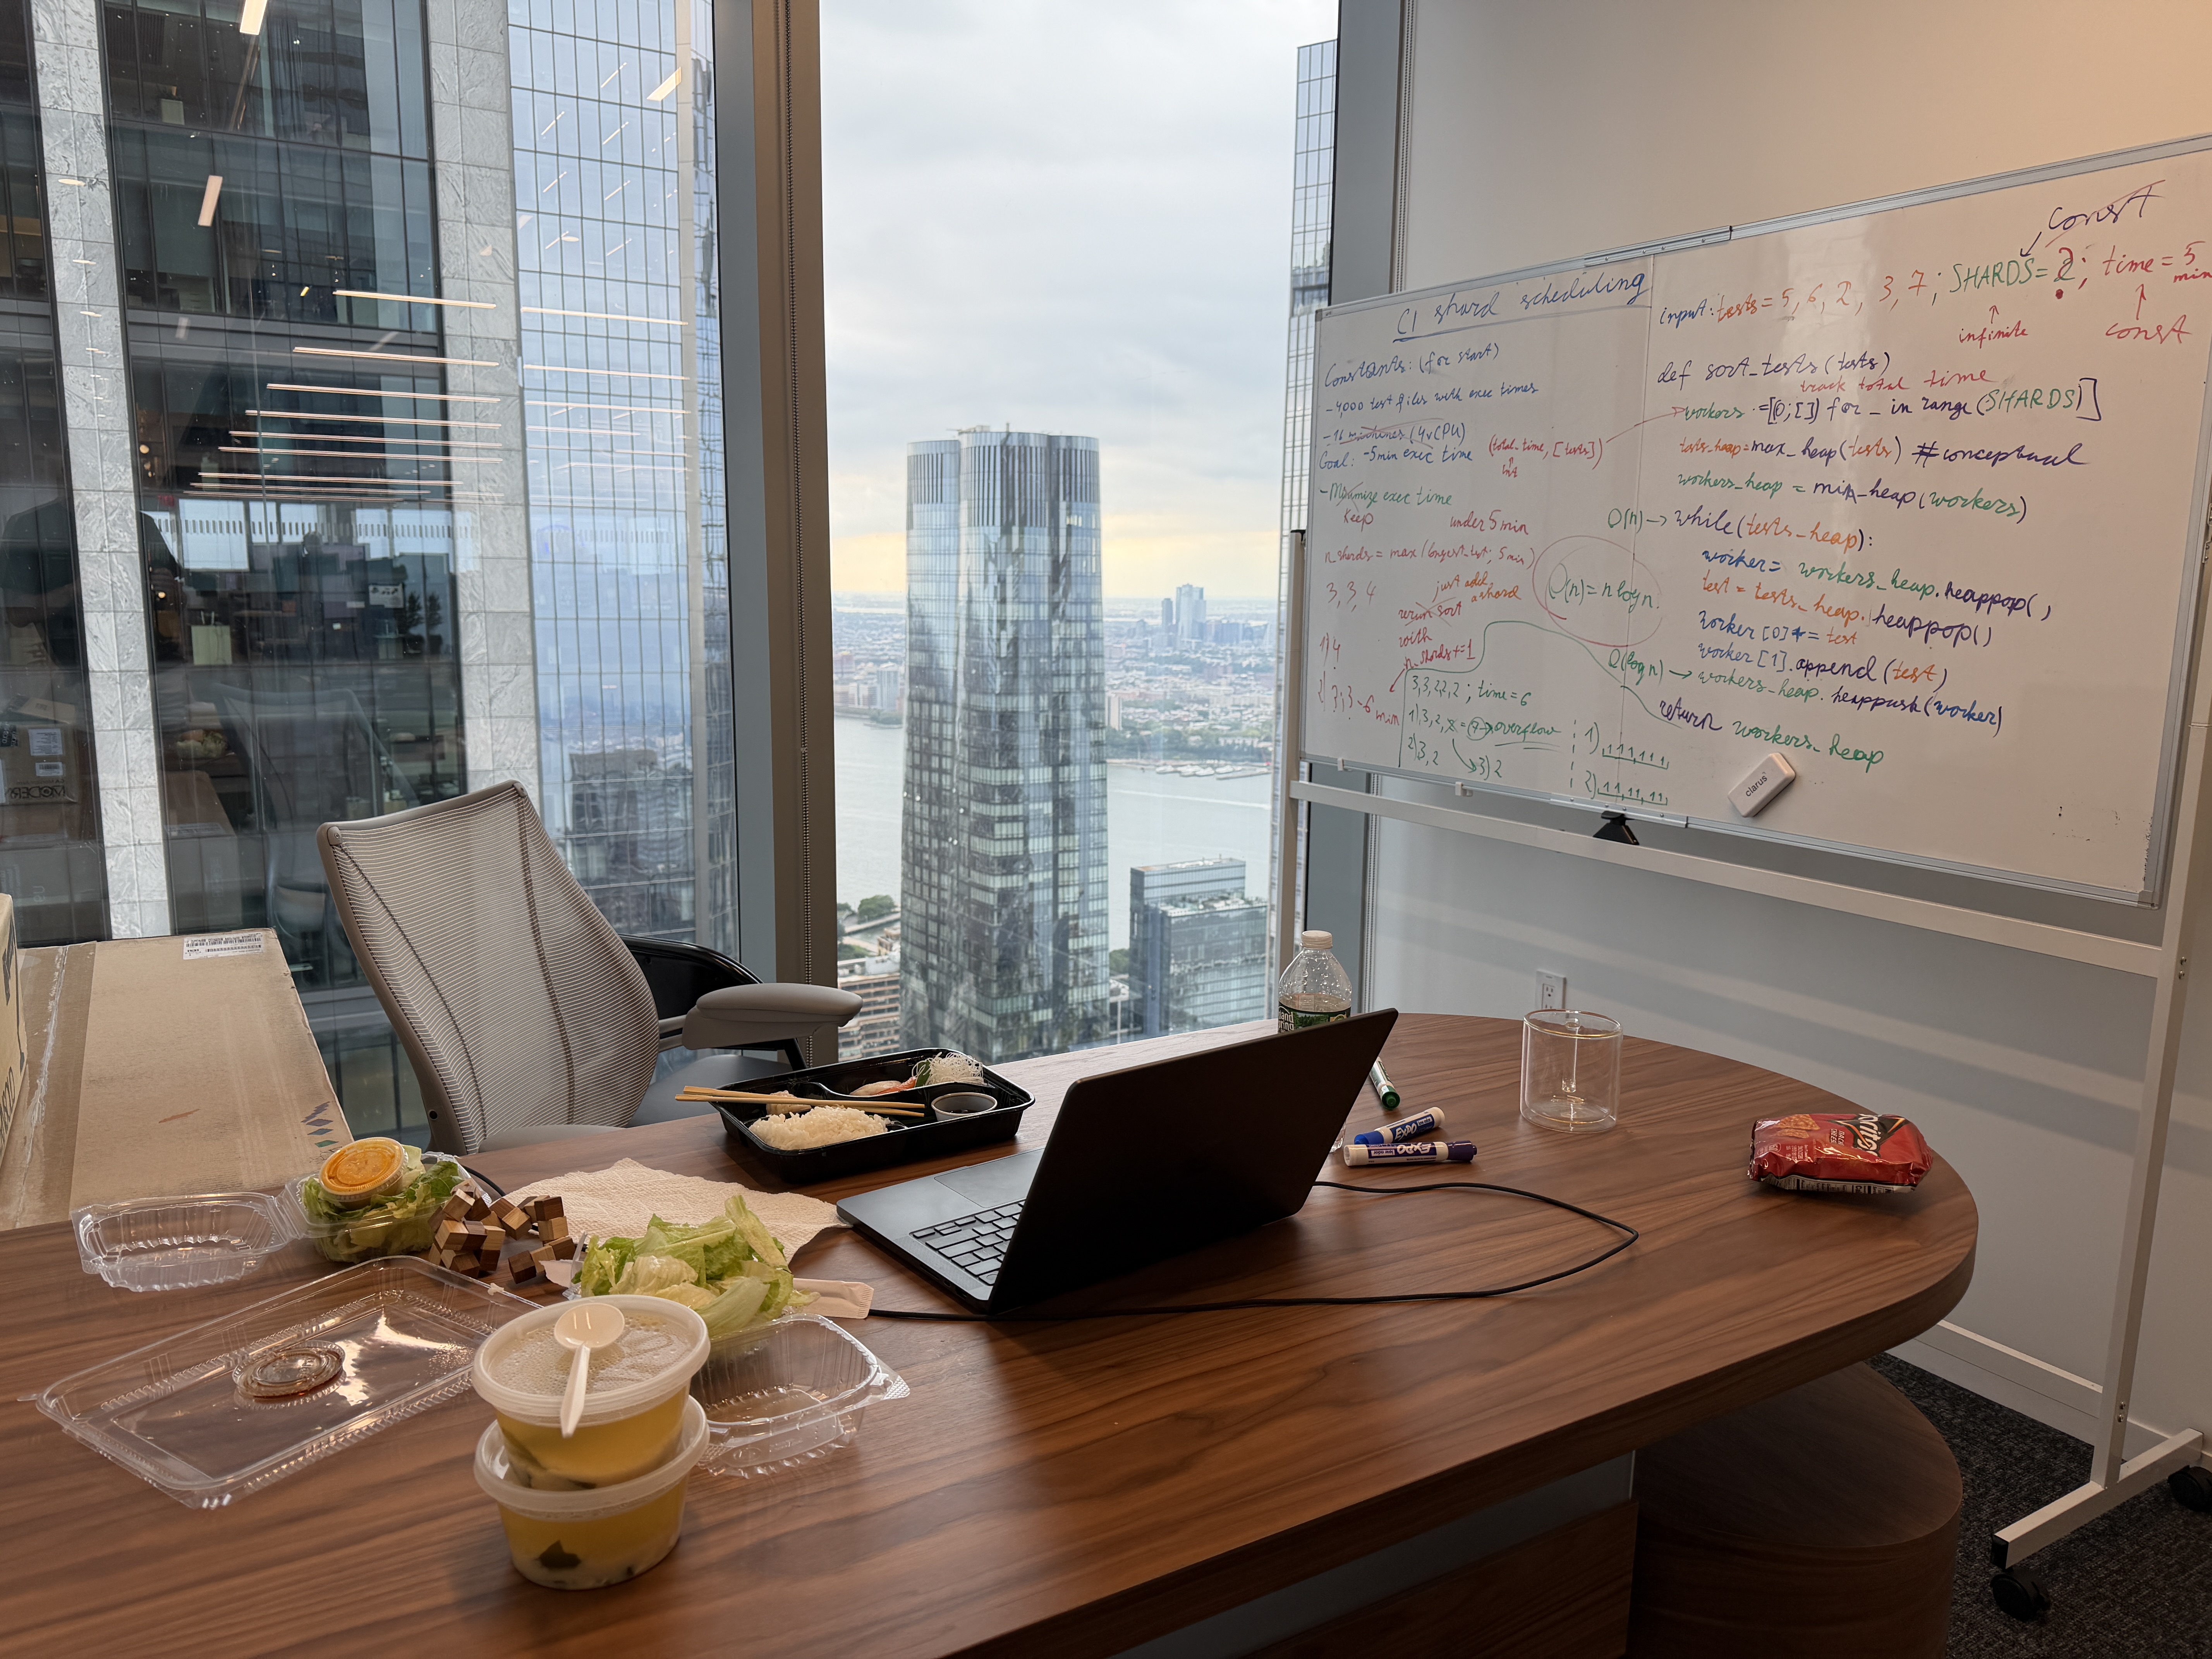 I used my brain instead of AI - now CI runs 70% faster
Sharding tests by duration with heaps, best-fit packing, and a balanced tree. Building a Rust implementation by hand, then using benchmarks and AI agents to improve throughput almost fivefold.
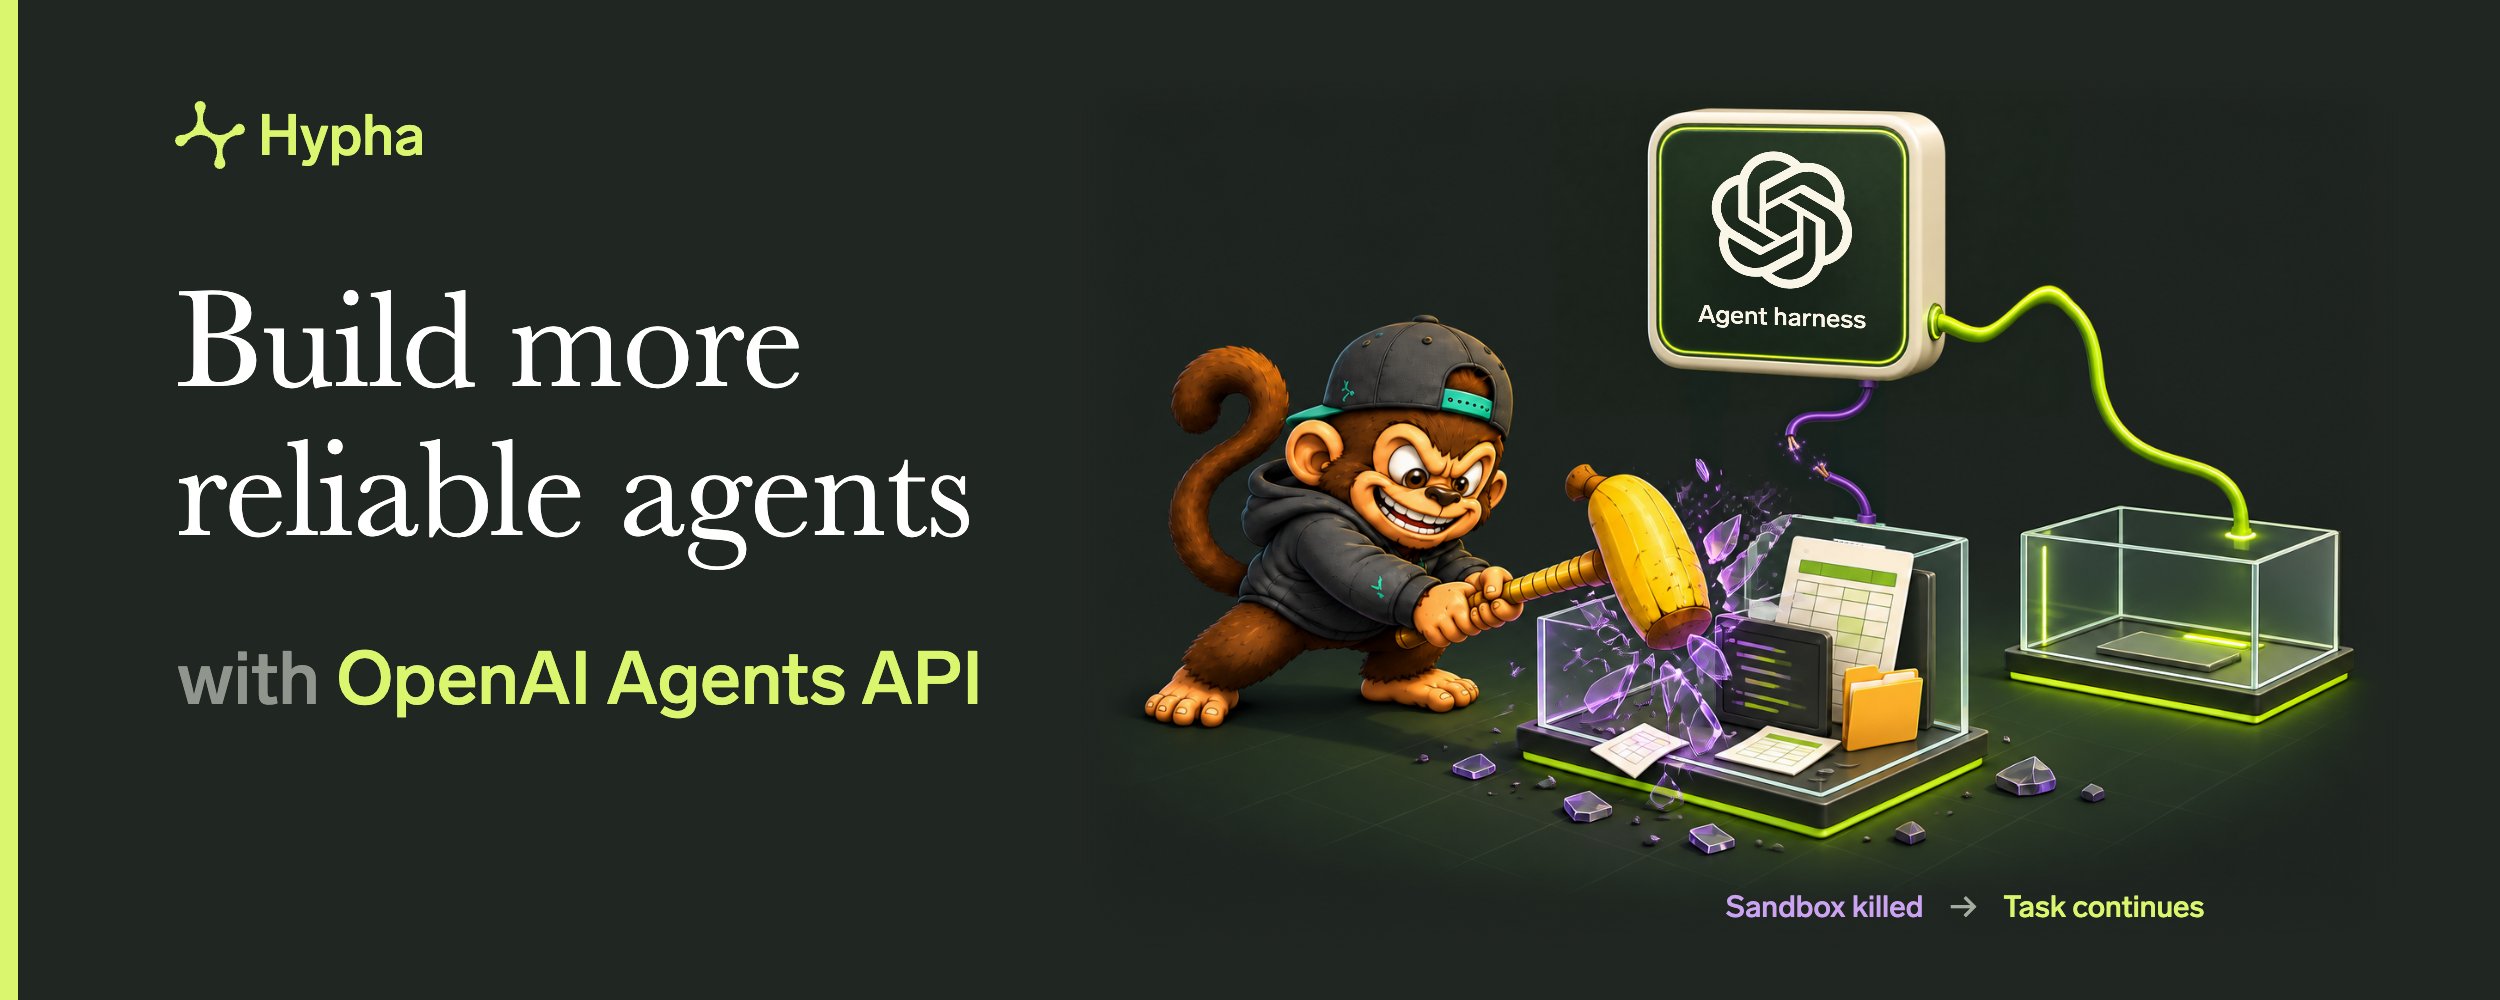 Path to more reliable agents: Migrating to OpenAI Agents API
OpenAI Agents API gives us a managed harness while keeping tool execution in a sandbox we control. Separating the two cut failed agent responses by 86%. How Hypha's architecture changed: a gateway for browser sessions and persistence, and a pool manager driving sandbox lifecycle from OpenAI and E2B webhooks.
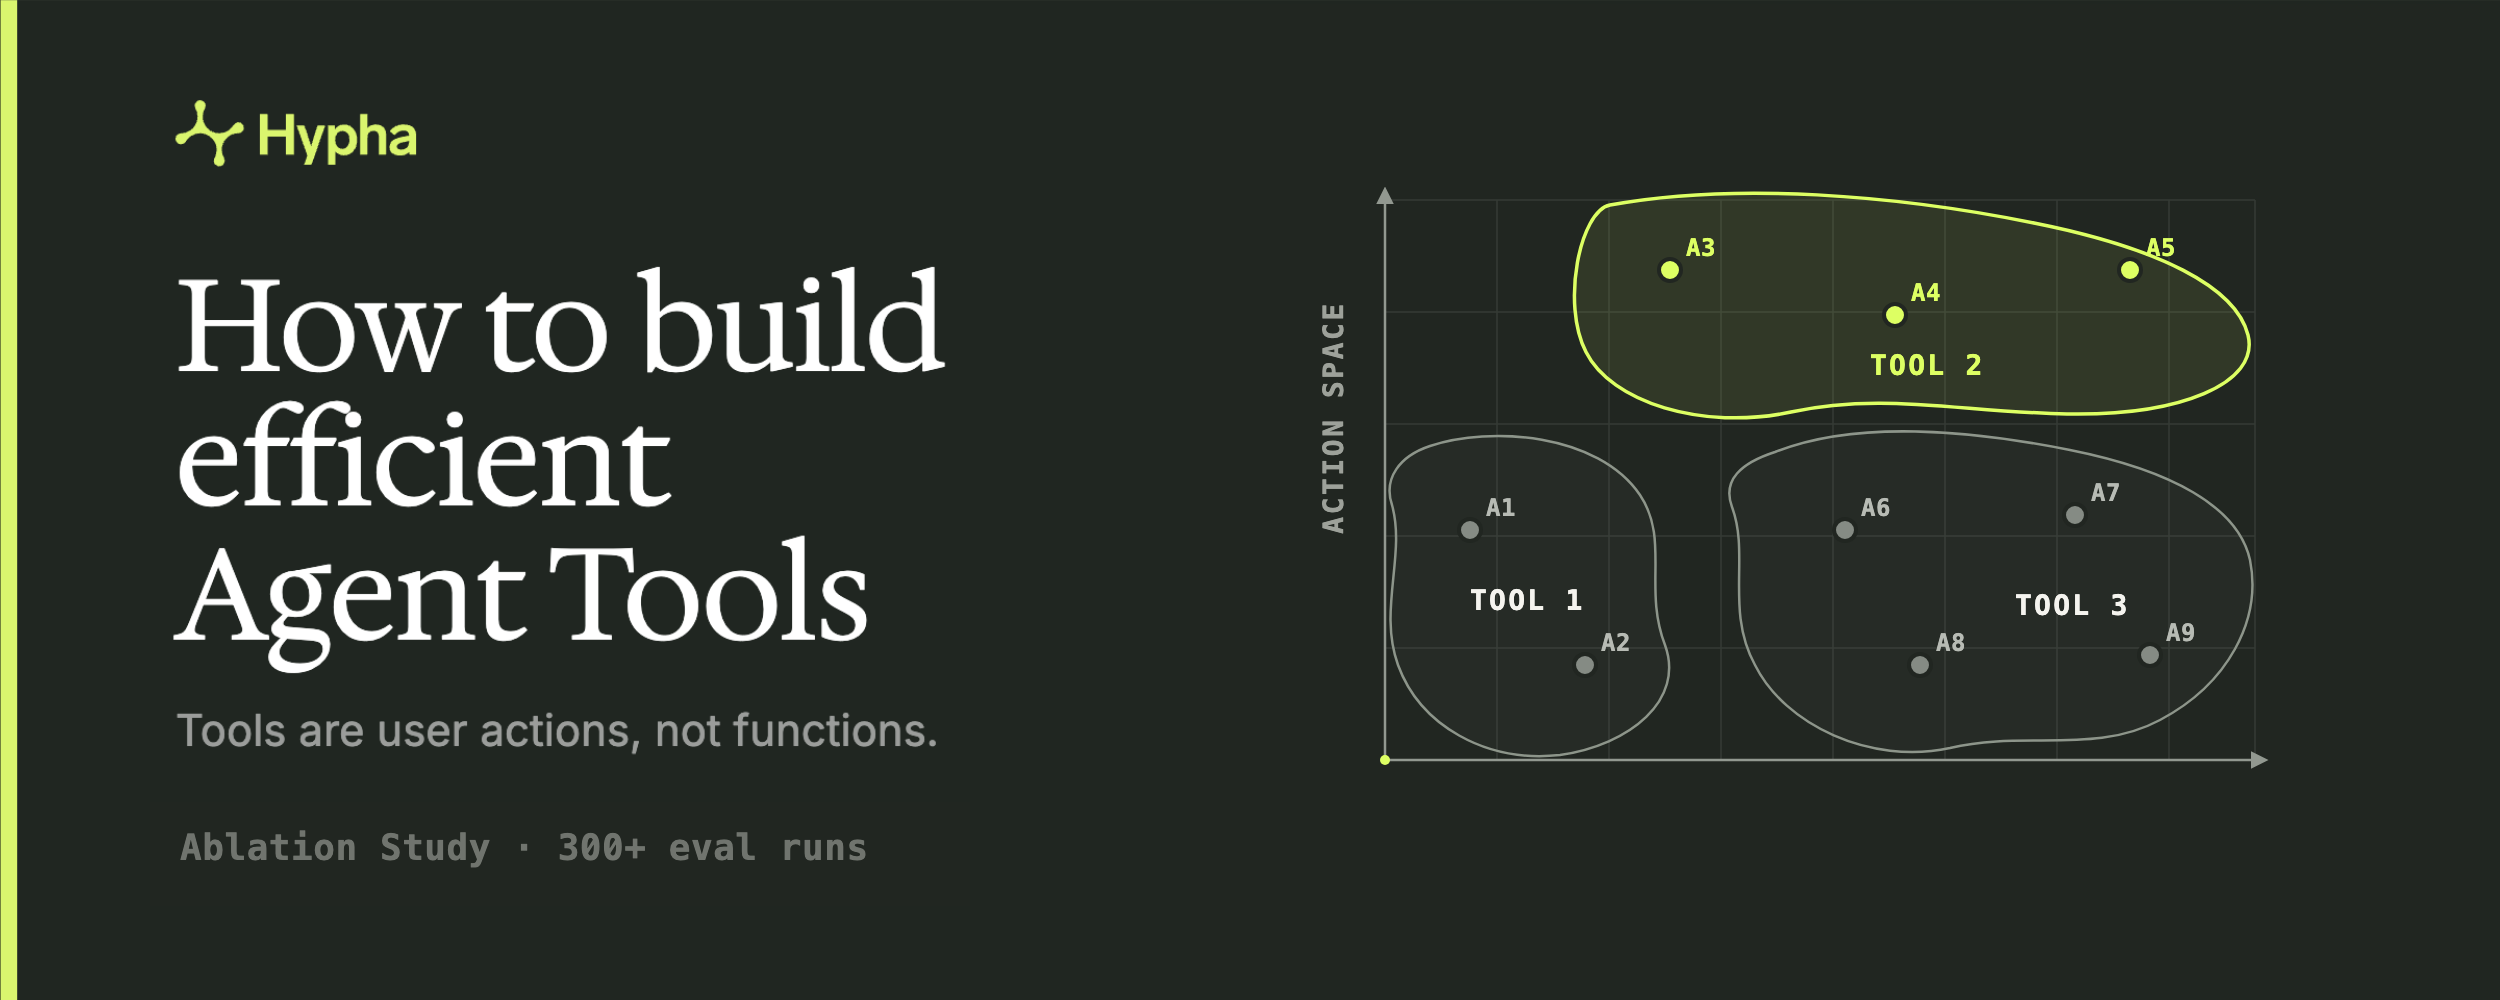 How to build efficient Agent Tools
Many engineers think of Agent Tools as functions, but they aren't. They are closer to user actions. Backed by a leave-one-out ablation study of Hypha's agent tools on a 55-question SQL retrieval eval: three financial data models, 300+ runs, three trials per case, on both the Codex SDK and the Claude Agent SDK.
 Building Browser Agents for Long-Horizon work
I contributed to the LLM in the Loop (LITL) and coding agents parts of this work.
More engineering posts on agent infrastructure, evals, and reliability are coming — most will run on the Hypha engineering blog and be indexed here. I post shorter notes on LinkedIn and X. Looking for the academic work? See Research.